 By Ilham Musyafa · June 16, 2025
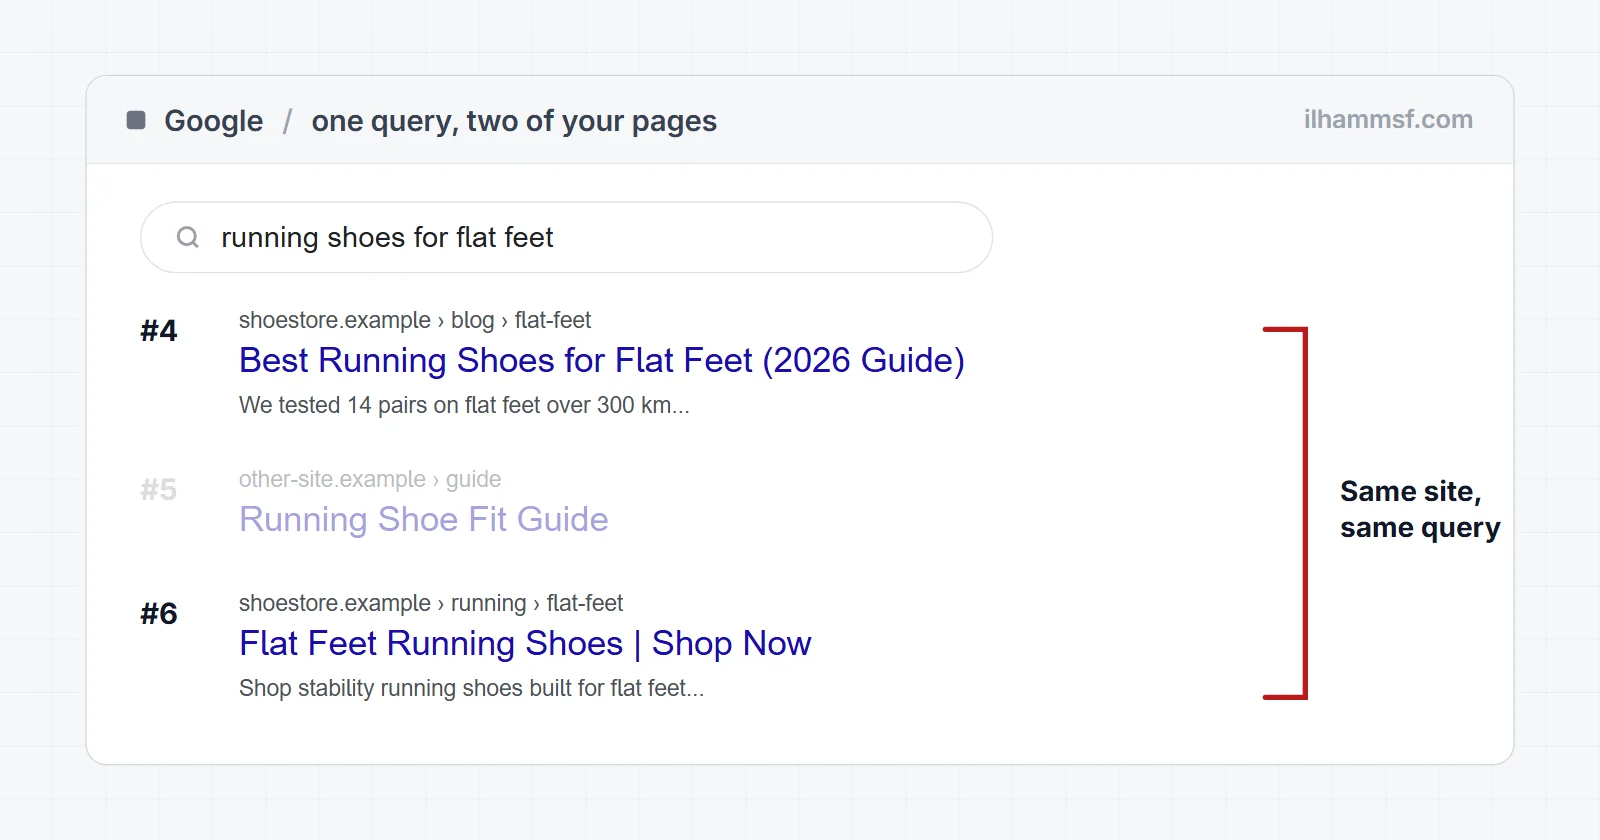
Keyword cannibalization happens when two or more pages on your own site compete for the same search intent, so instead of one strong page ranking well, you get several weaker ones taking turns and splitting the signals. It is a genuine problem, and it is also one of the most over-diagnosed issues in SEO. Two pages that mention the same keyword are not automatically cannibalizing each other. This guide shows you how to find real cannibalization in Google Search Console, how to choose the right fix for each situation, and which popular fixes tend to make things worse.
What is keyword cannibalization (and what it is not)
The key word is intent, not keyword. Cannibalization is when multiple pages try to answer the same question for the same kind of searcher. Google then has to choose between them, the choice can change from week to week, and neither page collects the links, clicks and internal signals it would get if everything pointed at one URL.
What it is not: two pages that share vocabulary while serving different intents. A page titled "best running shoes" (someone comparing products) and one titled "how to clean running shoes" (someone with a maintenance problem) both contain "running shoes", but they answer different questions and do not compete. Before you touch anything, ask whether the two pages serve the same intent or just use the same words.
Keyword cannibalization vs content cannibalization
Keyword cannibalization is the ranking symptom: your URLs trade places for one query. Content cannibalization is the cause: two or more pieces cover the same ground, so they compete for a whole set of queries. That is why most real fixes happen at the page level, not the keyword level.
Overlap that is not cannibalization
These look like cannibalization in a tool report, but are usually fine:
- Your homepage, about page and contact page all showing for a brand query.
- A category page and a product page ranking for a product name (browsing vs buying).
- Location pages for different cities that share a template but target different places.
- Two pages picking up impressions at position 40 or lower. Nobody sees either result.
- Two of your URLs listed together on page one. That double listing often earns more clicks than one result.
Is keyword cannibalization bad?
Only when it costs you something. The useful question is not "do two of my pages rank for this query?" but "is the overlap keeping the right page from ranking as well as it could?"
Signs it is actually costing you
- Position swapping. URL A ranks one week, URL B the next, and the site never settles on either.
- The wrong URL ranks. A thin old post shows up for a query your service page should own.
- Rankings stuck despite work. You improve a page and it does not move, because Google keeps testing a sibling URL in its place.
- Impressions split close to evenly between two pages for months, rather than one clearly leading.
If one page clearly owns the query and another occasionally brushes against it, leave it. Most "cannibalization" flags I see in tools are this kind of harmless overlap.
What causes keyword cannibalization
It rarely comes from one bad decision. It builds up over time:
- No keyword map, so new posts quietly repeat old ones.
- Posts written months apart by different people who never checked what already existed.
- CMS archives: tag, category and author pages that list the same posts.
- Templated service and location pages with the same copy and only the city swapped.
- Duplicate URL paths: parameters, trailing slash variants, HTTP and HTTPS, print versions.
- AI-assisted posts from similar prompts that answer one question in slightly different words.
How to find keyword cannibalization
A tool can give you a shortlist. Only your own Search Console data can confirm it. Here is the method I use, step by step.
Step 1: Filter the Performance report by query
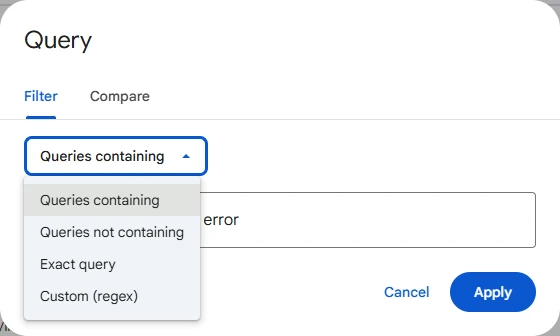
In Google Search Console, open Performance, then Search results, and set the date range to the last 3 months so you see a pattern, not one noisy week. Add a Query filter with the keyword you are worried about: Exact query for one phrase, Queries containing for all its variations.
Step 2: Open the Pages tab for that query
With the filter applied, switch the table below the chart from Queries to Pages, and turn on all four metrics in the chart. You now see every URL that received impressions for that query, with its clicks, impressions, CTR and average position.
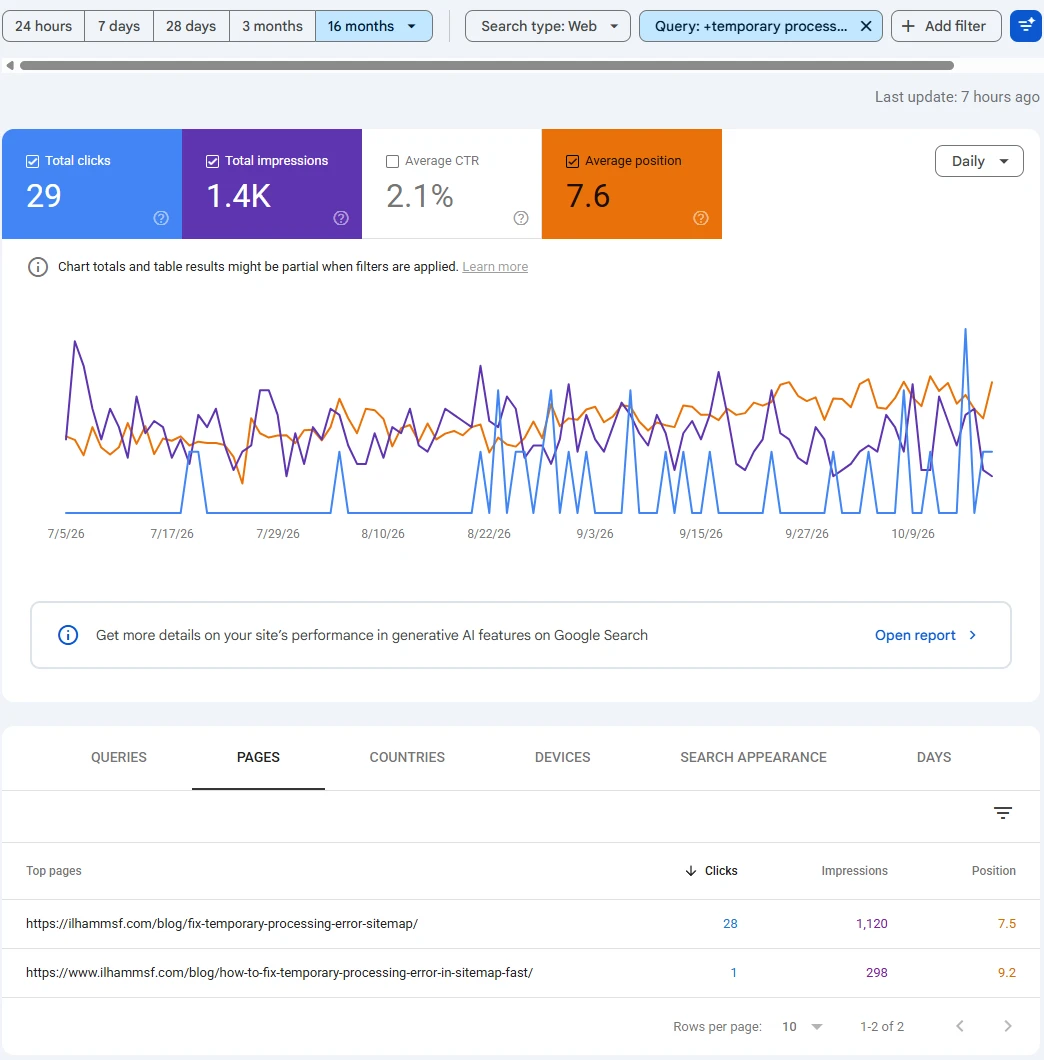
That second URL is not a competing article. It is the guide's old address from before this site moved off WordPress, and it now 301-redirects to the current guide. Its share, 298 against 1,120 impressions (a spread of about 0.27), is what a migration leaves behind, and it fades on its own as Google processes the redirect. Rule this case out first: if the second URL already redirects to the first, there is nothing to fix.
Read the table like this. One URL with almost all the impressions is normal. Two or more URLs with a meaningful share of impressions each is your candidate. A second URL with a handful of impressions at position 60 is noise.
My own SEO console automates exactly this. It groups queries where two or more pages received impressions and computes a "spread": impressions of the second page divided by impressions of the first. Near 0, one page clearly owns the query. Close to 1.0, two pages get almost the same exposure, which is worth a closer look. You can calculate the same ratio by hand from the Pages tab to sort a long list into "ignore" and "investigate".
Step 3: Compare dates to confirm swapping
Shared impressions can mean two pages showing at the same time, or two pages taking turns. To tell them apart, open the date filter, choose the Compare tab, and pick a pair of periods, such as the last 3 months against the previous 3 months (use 28 days if the change is recent). The Pages table then shows each URL's numbers for both periods side by side.
If page A led last period and page B leads now, that is the swapping fingerprint. For a closer look, filter by Page for URL A, note its position for the query in the Queries tab, then repeat for URL B.
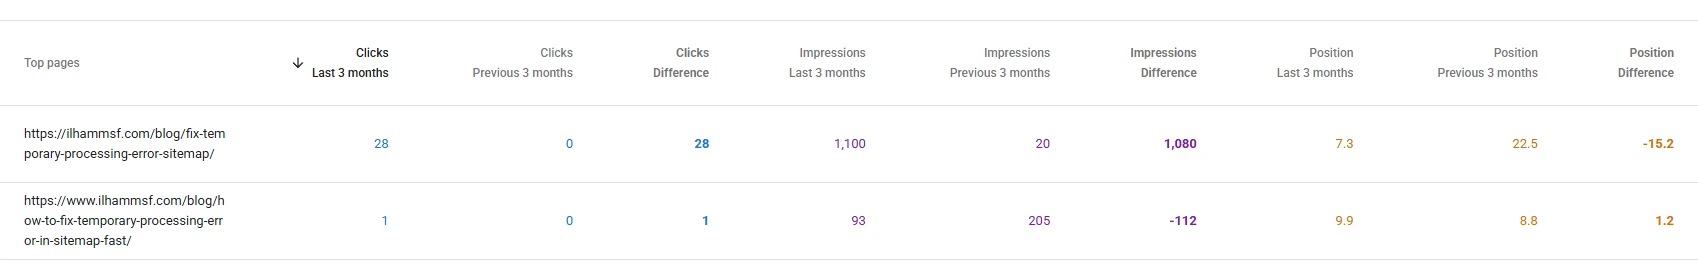
Search Console keeps 16 months of data and usually runs a couple of days behind, so do not judge a change you made yesterday (more in why Search Console seems not to update). Very rare queries are hidden for privacy, so some long-tail overlap never shows.
Step 4: Run a site: search
Search site:yourdomain.com keyword to see which of your pages Google associates with the topic, then search the keyword normally in a private window. It is a rough sanity check, not a ranking report, but it often reveals a forgotten tag archive or old post.
Step 5: Check what Google sees on both URLs
Before deciding which page should win, run both URLs through the indexability checker: it reports the status code, any redirect, robots.txt, noindex in the meta tag or X-Robots-Tag header, and the canonical. If one URL already canonicalizes or redirects to the other, Google is already consolidating them, and the flag is a reporting artifact, not a competition. If both return 200, are indexable and are self-canonical, the overlap is real.
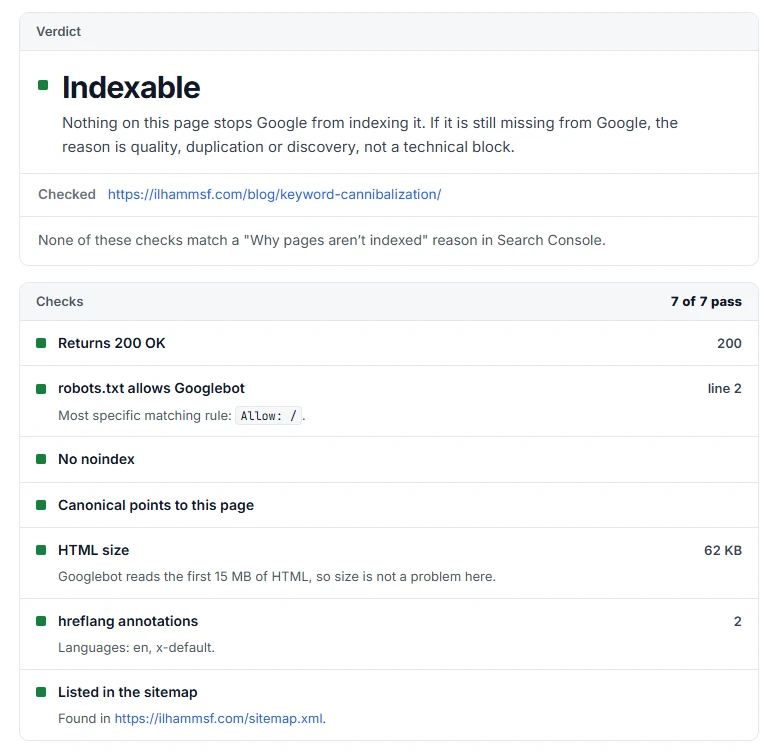
Triage checklist: is it real?
My rule of thumb, not a Google rule: treat it as cannibalization worth fixing only if all of these are true.
- The query matters to the business (it leads to leads, sales or an important page), not a random phrase.
- Both URLs held impressions for it in most weeks of the last 3 months.
- The impression spread between them is high, not 10 to 1.
- Positions swap or stall, rather than one URL holding steady.
- Both URLs are indexable and self-canonical, and they serve the same intent.
If any of these fails, write it down and check again next quarter. That one habit saves more traffic than any fix.
How to fix keyword cannibalization
There is no single fix. The right move depends on why both pages exist. Use this table to pick one, then read the matching section.
| Situation | Fix | What to check after |
|---|---|---|
| Two near-duplicate posts, same intent | Merge into one, 301 the weaker URL | Single-hop 301, survivor indexed, query rolls up to it |
| Both pages useful, intents drifted together | Differentiate titles, H1s and content | Each page ranks for its own query set |
| One page should own it, the other supports it | Internal links and anchors to the target | Target URL leads in the Pages tab |
| True variants (parameters, print, filters) | Canonical to the main URL | Google-selected canonical matches yours |
| Thin page with no traffic, links or purpose | Remove with a 301 to the closest page | No 404s from internal links |
| Overlap at low positions, low-value query | Leave it | Recheck next quarter |
Merge and 301 redirect near-duplicates
When two pages cover the same ground, combine them. Pick the survivor first: usually the URL with more backlinks, more clicks, or the cleaner slug. Fold the best sections of the other page into it, then 301 redirect the old URL to the survivor. Google's own guidance treats a permanent redirect as a strong signal that the target should be the canonical URL (redirects and Google Search).
Write the rule with the redirect generator: paste the old and new URL pairs, for example /blog/website-audit-tips/ to /blog/website-audit-that-leads-to-action/, and it outputs the rule for .htaccess, nginx or Cloudflare. It also flags chains: if the old URL was already redirected once (A to B), and you now redirect B to C, point A straight at C so every old URL lands in one hop.
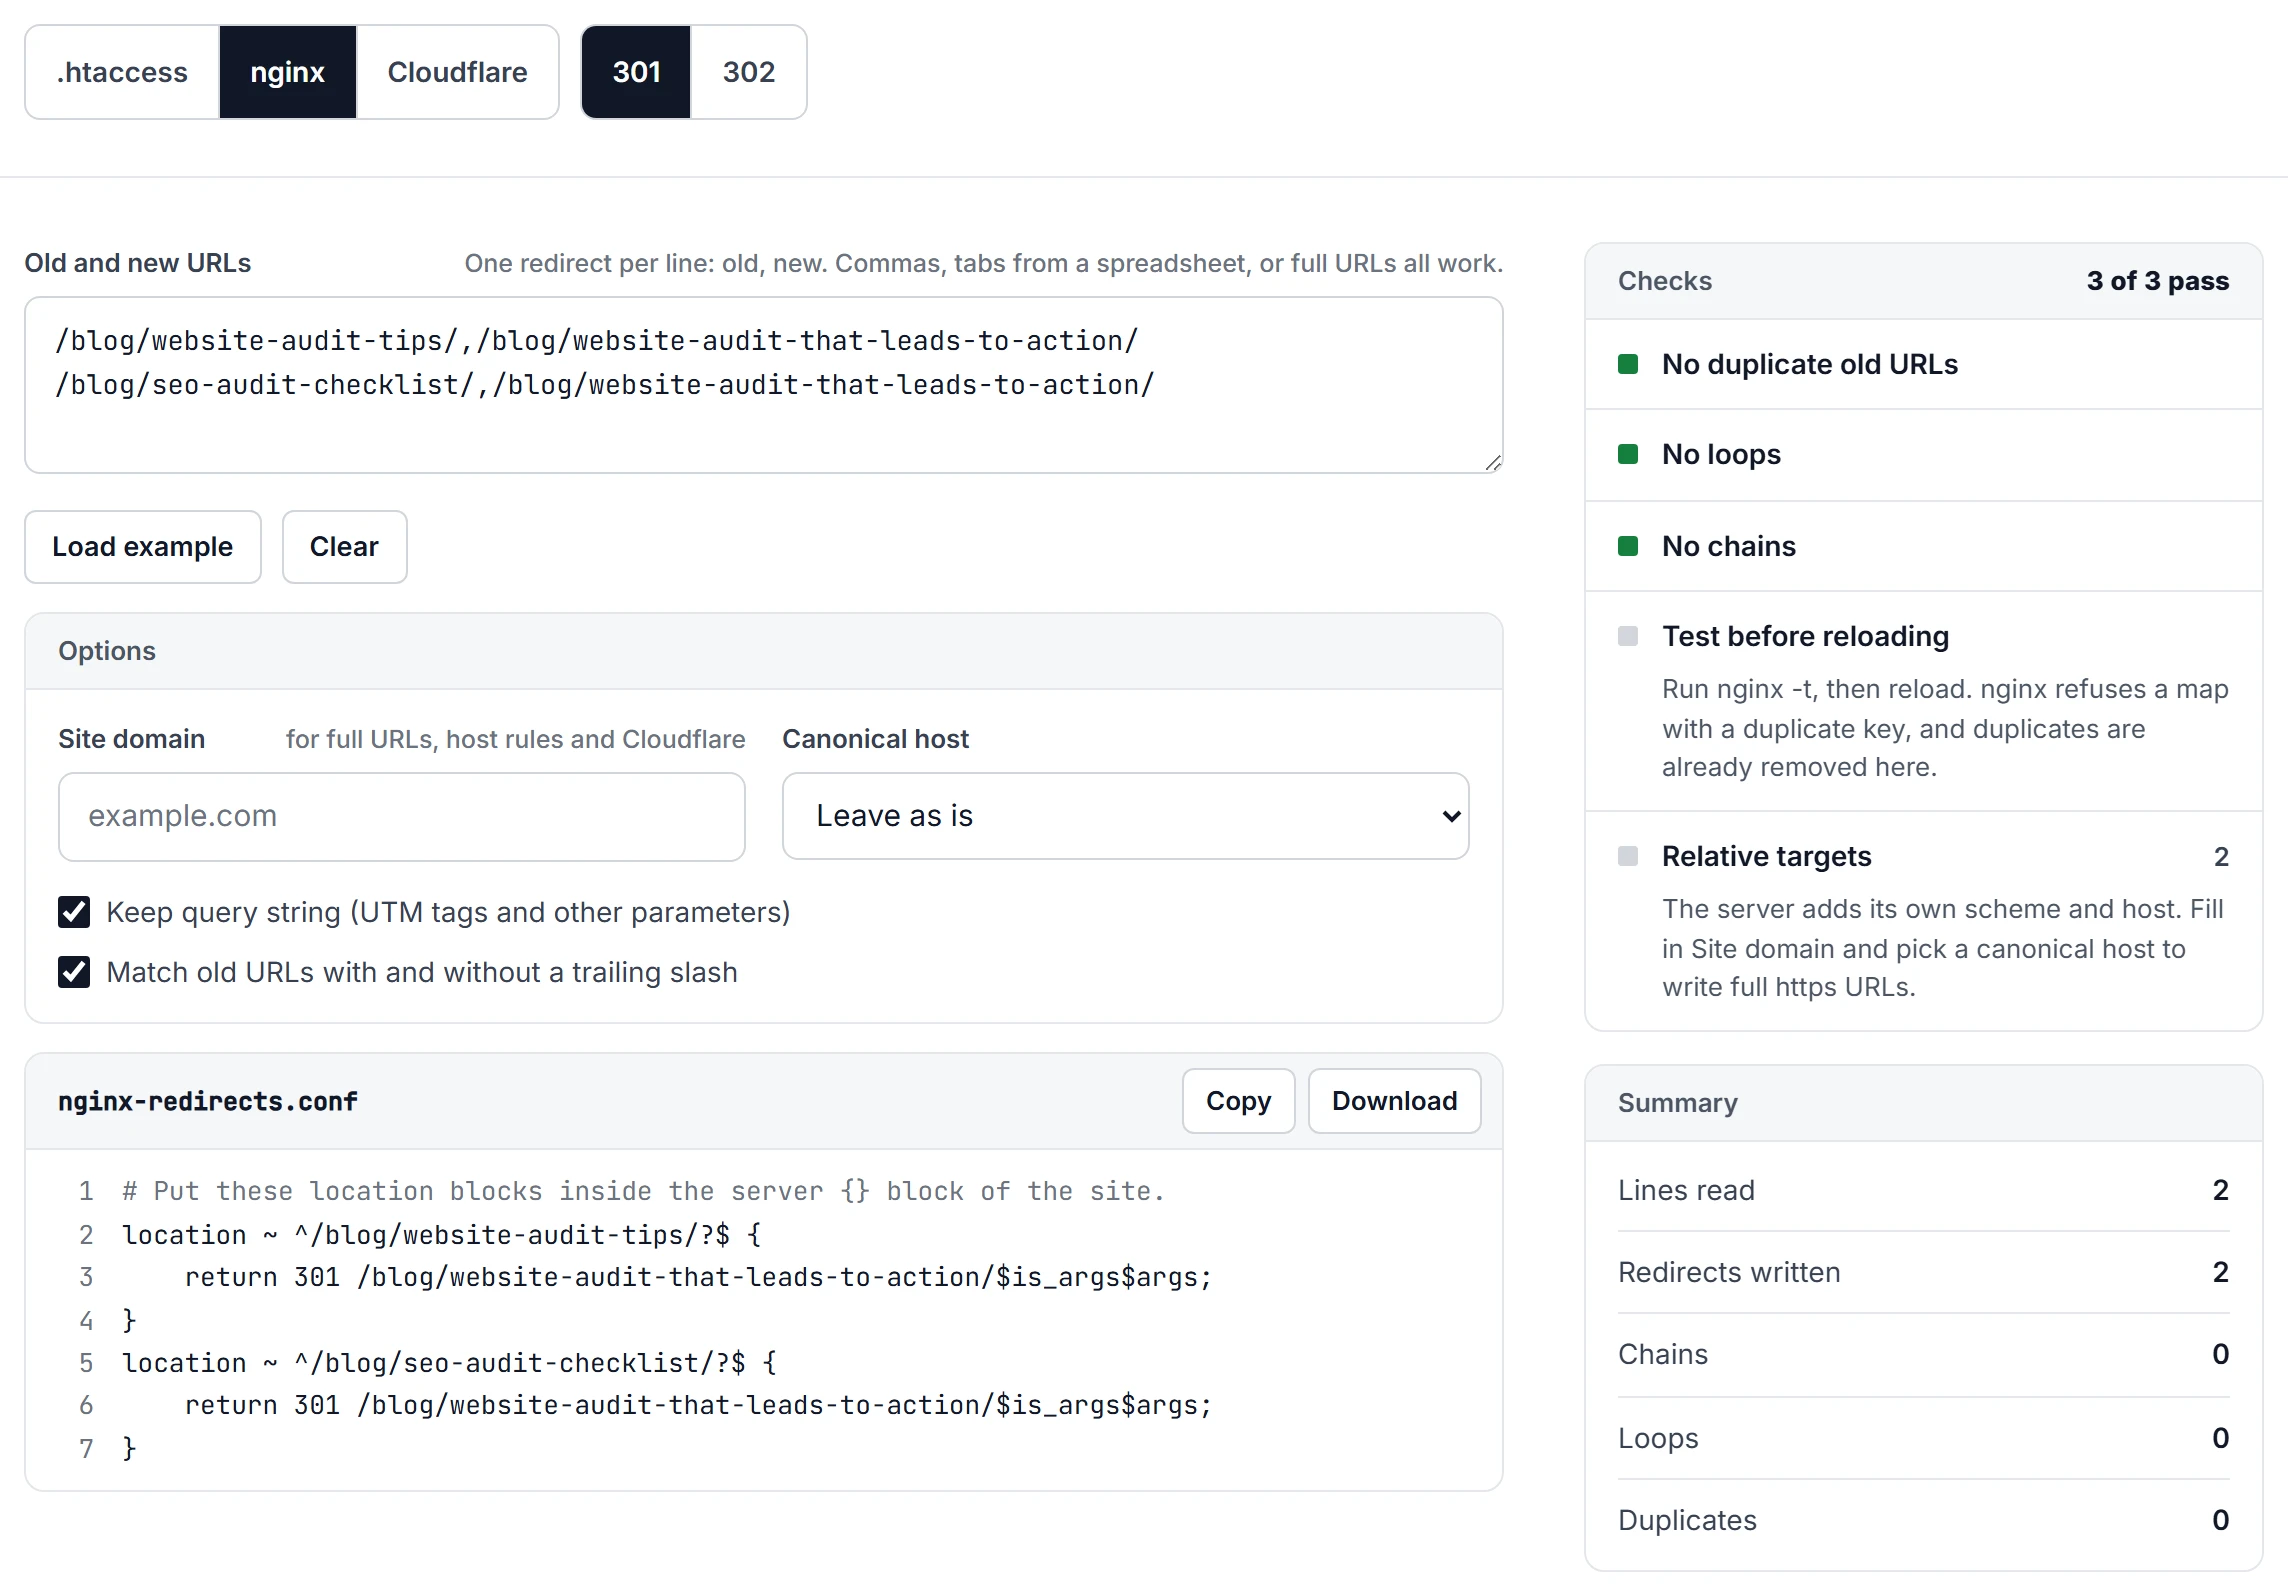
The redirect is only half the job. After merging:
- Update internal links that pointed at the old URL so they point at the survivor directly.
- Remove the old URL from your XML sitemap.
- Run the old URL through the indexability checker again: one 301 to the survivor, and the survivor returns 200 with a self-referencing canonical.
- Keep the redirect. Google's site move guidance recommends at least a year, and there is rarely a reason to remove one.
Differentiate both pages
Sometimes both pages deserve to exist, they have just drifted toward the same intent. Decide what each is for in one sentence ("a checklist people can copy" vs "what an audit costs"), then rewrite the title, H1, intro and headings to match. Move sections that belong to the other page, and link between them with descriptive anchors.
Titles are where the difference shows first. "Website audit checklist (free template)" and "How much does a website audit cost?" read as two different answers. Check both in the SERP preview tool so the distinguishing words are not cut off.
Consolidate signals with internal links
When one page should own a query and the other supports it, say so with your own links. Link from the supporting page and other related pages to the target, with anchor text that describes the target's topic, and stop using that anchor for the supporting page. Internal links are the signal you control completely, and on small sites they are often enough to settle a swap.
Canonical tags, only for true variants
A rel="canonical" tag tells Google which URL you prefer when several URLs show the same or nearly the same content: parameter URLs, sorted or filtered views, printer versions, the same product in several categories. Google treats it as a hint, not a directive, and may pick a different canonical if your other signals disagree (consolidating duplicate URLs). It is not a tool for two different articles that happen to target one keyword. After adding one, use URL Inspection in Search Console on the variant and compare "User-declared canonical" with "Google-selected canonical".
Fixes that usually backfire
These are common reactions to a cannibalization flag, and why they tend to cost traffic:
- Deleting without a redirect. The URL becomes a 404 and its backlinks stop counting for you. Its rankings do not move to the other page on their own.
- Noindex as the fix. The weaker page disappears, but its links and history do not transfer to the page you want to rank.
- Canonical between two different pages. Google often ignores it, so nothing changes. If it does follow it, the canonicalized page vanishes for queries only it answered.
- De-optimizing the stronger page. Removing the keyword from one title to "make room" usually just lowers both.
- Mass redirects from a tool export. Dozens of unreviewed redirects create chains, merge different intents, and hide which change caused a drop.
- Merging different intents. A comparison page folded into a how-to guide serves neither searcher, and often ranks worse than either original.
A worked example
This example is hypothetical, but the pattern is common on small business blogs.
Say a site has two posts written 18 months apart: /blog/how-to-audit-a-website/ and /blog/website-audit-checklist/, both for people auditing their own site. Filtered by the query "website audit checklist", the Pages tab shows both URLs with impressions every month for 3 months, the second at about 80% of the first, so the spread is around 0.8. Compare mode shows the older post led two months ago and the newer one leads now, with both stuck on page two.
The triage checklist passes: the query matters (it is the path into the audit service), both URLs are indexable and self-canonical, and both answer the same question. The fix is a merge.
The older post has more backlinks and the cleaner URL, so it survives, and the newer post's checklist moves in as its own H2. The newer URL gets a single 301, internal links are updated, and it leaves the sitemap. An indexability check confirms one 301 hop and a self-canonical survivor.
Then comes the part people skip: waiting 4 to 8 weeks before judging. You are looking for one URL in the Pages tab for the query, holding a steadier position than either page held alone. If the survivor does not improve, the problem was never the overlap, and the next step is the content itself, which is where a proper website audit starts.
How to prevent keyword cannibalization
Cannibalization is mostly a planning problem, so the durable fix happens before you publish.
Keep a simple keyword map
A keyword map is a sheet that assigns one primary intent to each URL. Five columns are enough:
| URL | Primary intent | Primary query | Secondary queries | Status |
|---|---|---|---|---|
| /services/website-audit/ | Hire someone | website audit service | seo audit service | Live |
| /blog/website-audit-checklist/ | Do it myself | website audit checklist | seo audit steps | Live |
| /blog/website-audit-cost/ | Compare prices | website audit cost | seo audit pricing | Planned |
Every new page gets a row before it gets written. If the primary query already belongs to a live URL, you update that page instead of writing a new one. If you want help building one from real data, that is what keyword research is for.
Check before you publish
Before writing a new post, search your Search Console for the query you plan to target. If a URL already gets impressions for it, improve that page, write for a clearly different intent, or skip it.
Run a quarterly check
Every quarter, run Steps 1 to 3 on your 20 to 50 most important queries and note any where a second URL now holds a real share of impressions. Catching drift early means a small internal link change instead of a merge. On larger sites, export the data, calculate the spread for every query with two or more URLs, and review only the ones near 1.0.
Frequently asked questions
What is keyword cannibalization in SEO?
Keyword cannibalization is when two or more pages on the same site compete for the same search intent, so Google keeps switching between them and neither ranks as well as one consolidated page would. It is about intent, not shared words. Two pages that use the same keyword for different purposes are not cannibalizing each other.
Is keyword cannibalization bad?
It is bad when positions swap between two URLs or a weak post outranks the page you want to rank. It is harmless when one page clearly owns the query, both show together on page one, or the pages serve different intents.
How do I find keyword cannibalization in Google Search Console?
Open Performance, filter by the query, switch to the Pages tab, and look for two or more URLs with a meaningful share of impressions. Then use Compare mode on the date filter to see whether they trade places over time.
Should I use a 301 redirect or a canonical tag to fix cannibalization?
Use a 301 redirect when you merge two pages and the old one no longer needs to exist for visitors. Use a canonical tag only when both URLs must stay accessible and show essentially the same content, such as parameter or filtered versions. A canonical between two different articles is usually ignored by Google.
Can two of my pages rank for the same keyword without a problem?
Yes. Two of your pages on page one together usually means more clicks, not fewer. It is also fine when one page clearly leads and the other only collects a few impressions at low positions.
Is there a free keyword cannibalization checker?
Google Search Console is the free checker, because it shows which of your URLs actually received impressions for each query. Other tools build a shortlist faster but flag many harmless overlaps, so confirm every case in Search Console first.
What is the difference between keyword cannibalization and keyword stuffing?
Keyword stuffing is repeating a keyword unnaturally inside one page. Keyword cannibalization is a site structure problem where several pages target the same intent. One is about a page's text, the other about how your pages relate to each other.
What is keyword cannibalization in Google Ads?
In Google Ads the term usually refers to your own campaigns or ad groups targeting the same keywords and competing to serve the ad, or to paid ads taking clicks your organic result would have earned anyway. It is a different problem from SEO cannibalization and is managed in the ad account, not on your pages.
If you suspect your own pages are competing and want a clear map of what to merge, keep or redirect, a website audit will lay it out, or take a look at my SEO services if you would like it sorted for you.